TigerTeam
Big builds.
Aligned agents.
No babysitting.
Tiger Team puts a frontier-model PM in charge of a fleet of cheap coding agents — every ticket graded, routed and verified, so big builds land without the frontier token bill, and without anyone watching the queue.
on first pass
for a whole product
evening + afternoon
Case evidence: ASCII City — a real product shipped with TigerTeam · Aug 2026
The problem
Flat pricing for lumpy work
One-agent builds have no seam: a frontier model chasing a lint error bills at the rate it charged for the architecture decision an hour earlier — and when the context fills, the plan goes with it.
Route everything to a frontier model
Routine C1/C2 work burns premium tokens. Finance sees the invoice at the end of the month — and no way to explain it.
Route everything to a cheap model
The hard tickets come back as rework, review load, and quiet defects. Engineering pays for it in the incident channel.
38 real tickets — one shipped product
Most of a backlog is routine. A thin sliver carries all the judgment — and single-model routing makes you overpay at both ends.
Difficulty has a distribution. Your spend should follow it.
The mechanism
A routing machine with a guarded gate
You — direction + consent
PM — frontier model
Plans the build · turns C3 problems into C2 tickets · reviews, arbitrates, merges.
Ticket board
A lane may claim a ticket only up to its complexity cap.
Worker fleet — 6 containers in parallel
Each worker: own git worktree + fresh container
codex · grok · deepseek · GLM · kimi · gemini · …
PM gate
Accept / reject / answer — always through guards · no auto-accept, no merge on green.
Main
Stays green.
Failure paths — designed up front
Worker stuck → incomplete report → re-queued. Happened 4× — cost minutes, not rework.
A lane that fast-fails twice stops itself.
Per-ticket timeout. No runaway meters.
The wrapper routes; it never decides — a green test suite is not consent to merge.
Proof — routing
87% of the work never touched a frontier model
of 38 shipped tickets were built by low-cost models — 22 by DeepSeek V4 Flash, 11 by Grok.
Share of 38 tickets — DeepSeek 58% · Grok 29% · Opus 13%
Ticket mix by complexity grade
The single C3 ticket — the integration step, where all the judgment lived — went to the frontier model. It never saw a ticket below its pay grade.
Source: .tigerteam/logs/attempts.jsonl + git log — ASCII City repo, 2026-08-23 → 2026-08-24
Case study — shipped with TigerTeam
ASCII City: empty repo to 60 fps in two sittings
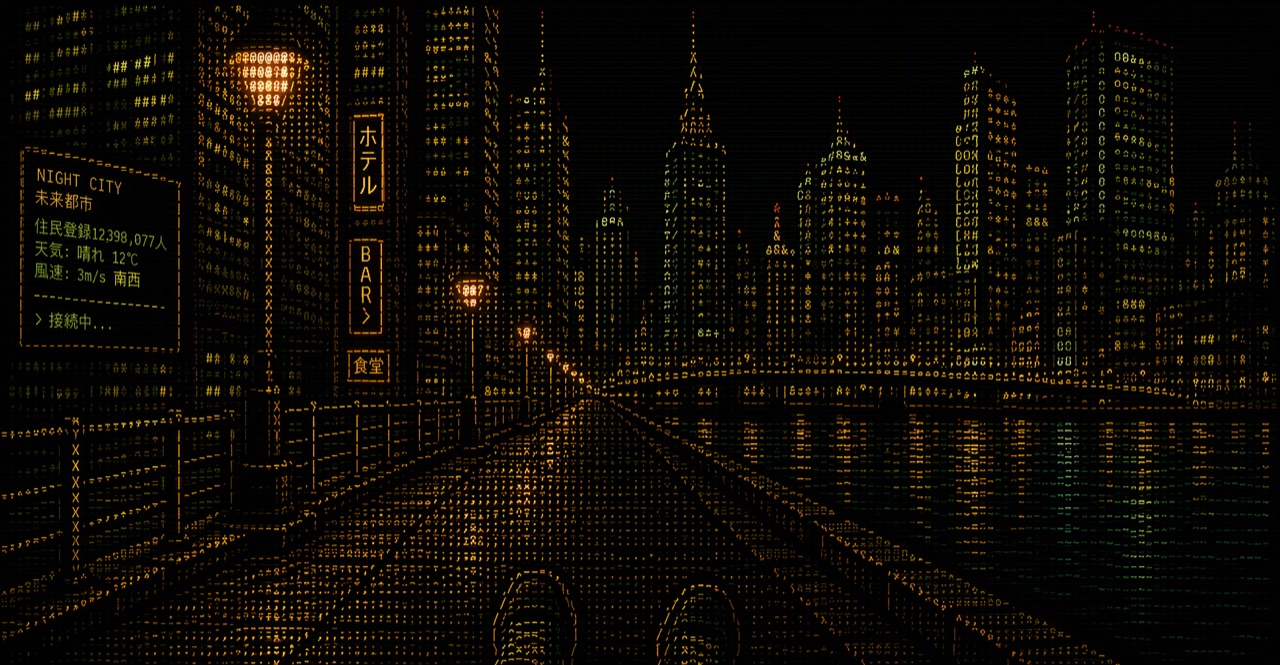
213×60 cells · RTX 3090
+ 7,803 roads
~8K lines of source
all green
across 49 attempts
reading diffs + gates
Wall clock
Proof — quality
49 attempts in. 37 clean merges out.
First-pass acceptance
across 38 boarded tickets
This acceptance rate at this speed comes from the gate: a merge happened only after the PM re-ran the tests inside the worker’s own container.
- ↳ 4 × incomplete self-reports → re-queued — cost minutes, not rework
- ↳ 6 × killed by PM — staging incident, ~105 s each · strike-free restart
- ↳ 1 rework — a spec bug on the PM side (T-0034), not a model error
Source: .tigerteam/logs/attempts.jsonl + board/done — ASCII City repo, 2026-08-23 → 2026-08-24
The guardrails
The guardrails are the speed
Four mechanisms keep the fleet safe at full throttle — no babysitting required.
Isolation
Every ticket runs in its own git worktree, on its own branch, inside its own container. Nothing touches main by default.
Verification
Acceptance criteria are runnable commands, not adjectives. Accepts and the full suite run in a dedicated staging worktree — main only ever fast-forwards from a verified staging.
Failure
A stuck worker hands off with an INCOMPLETE report instead of thrashing. A lane that fast-fails twice stops itself. Every ticket has a timeout.
Recovery
The board is durable state, not a session: STATE.md is the cold-start checkpoint, the event cursor queues while no PM is attached. Staging broke on merge #1: six workers killed, fixed, relaunched in ten minutes. Strike-free.
The economics
Cost control is built into the routing
Complexity caps
Frontier models only see tickets the cheap lanes may not claim — and the PM’s central move is turning a C3 problem into a C2 ticket by locking the decision into the ticket text.
Per-ticket timeouts
Every attempt has a hard ceiling. The median ticket landed in 4.8 minutes; the longest took 12.9.
Self-stopping lanes
Two fast failures and a lane parks itself instead of burning budget on a doomed approach.
Honest handoffs
A worker that cannot finish reports INCOMPLETE and re-queues — 4 handoffs in practice, each costing minutes.
What a whole product cost in time
6 containers × 2 CPU on a 12-core host — commodity hardware
No dollar figure was logged: two of the three models ran on flat subscriptions, only one was metered. The caps did the controlling — spend was shaped before it happened, not explained after.
Source: .tigerteam logs + DeepInfra-metered model only — ASCII City repo, 2026-08-23 → 2026-08-24
What this means for you
For the CTO
Judgment stays with the PM — no auto-accept, no merge on green. Main only fast-forwards from a verified staging.
One audit log for every mutation — yours, the PM’s, the fleet’s. Runs in your own Azure VNet, no public ingress.
Quality at volume: 37 of 38 tickets accepted on first pass, 262 unit tests and an e2e suite green.
The board is durable state, not a session — a dead session or an ephemeral PM is a non-event by design.
For the CFO
Spend follows difficulty: 87% of tickets went to low-cost models; premium tokens bought judgment only.
A whole shipped product cost ≈4 h of model compute, on commodity hardware.
Failure is cheap by design — handoffs and self-stopping lanes cost minutes, not sprints.
No babysitting: the board nudges the PM when tickets wait — review and answer from a phone.
The leverage lives in the tickets —
the model is interchangeable.
TigerTeam · Evidence: ASCII City repo logs (.tigerteam/, git) · 2026-08-23 → 24